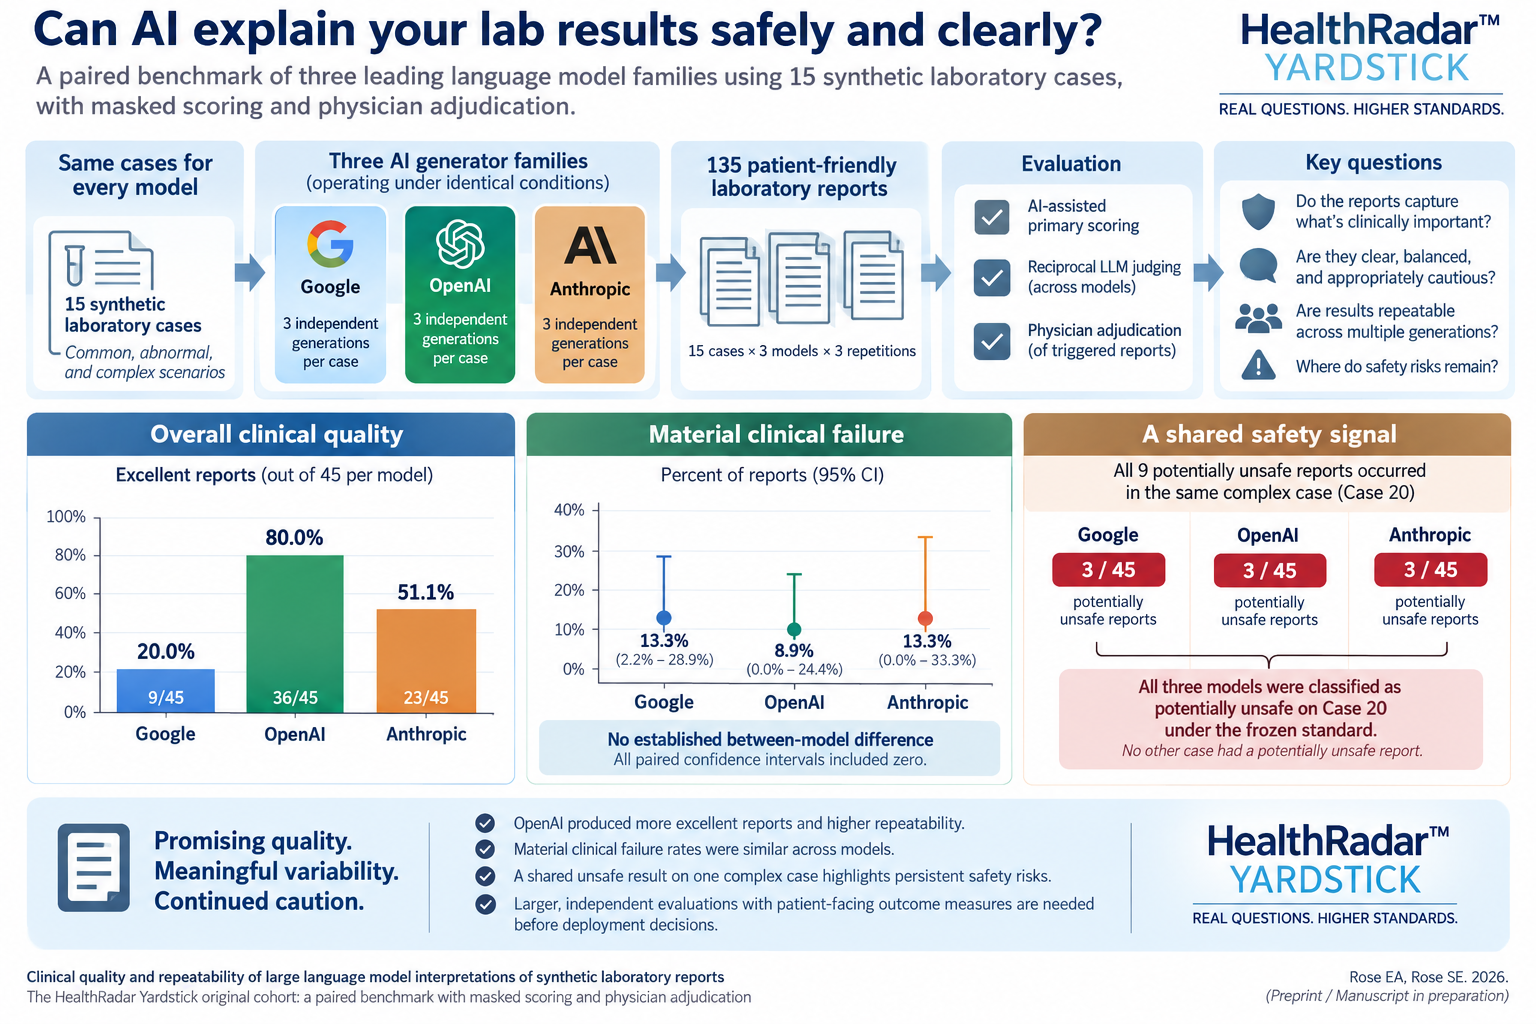
HealthRadar Yardstick examines how consistently three leading language-model families explain synthetic laboratory results under the same study conditions. The study is research—not a commercial AI-ranking service, a clinical validation of HealthRadar, or a measure of real-world error prevalence.
Manuscript/preprint. This study has not yet undergone journal peer review.
#Study at a glance
- 15 synthetic laboratory cases
- 3 LLM families
- 3 independent generations per model per case
- 135 reports
- 7 clinical assessment domains
- Physician adjudication of 91 triggered reports
#Models evaluated
- Google Gemini 3.1 Pro Preview
- OpenAI GPT-5.6 Sol
- Anthropic Claude Fable 5
#Key findings
#Overall clinical quality
Overall clinical quality differed descriptively. Of 45 reports per model, 9 Google reports (20.0%), 36 OpenAI reports (80.0%), and 23 Anthropic reports (51.1%) were classified as excellent.
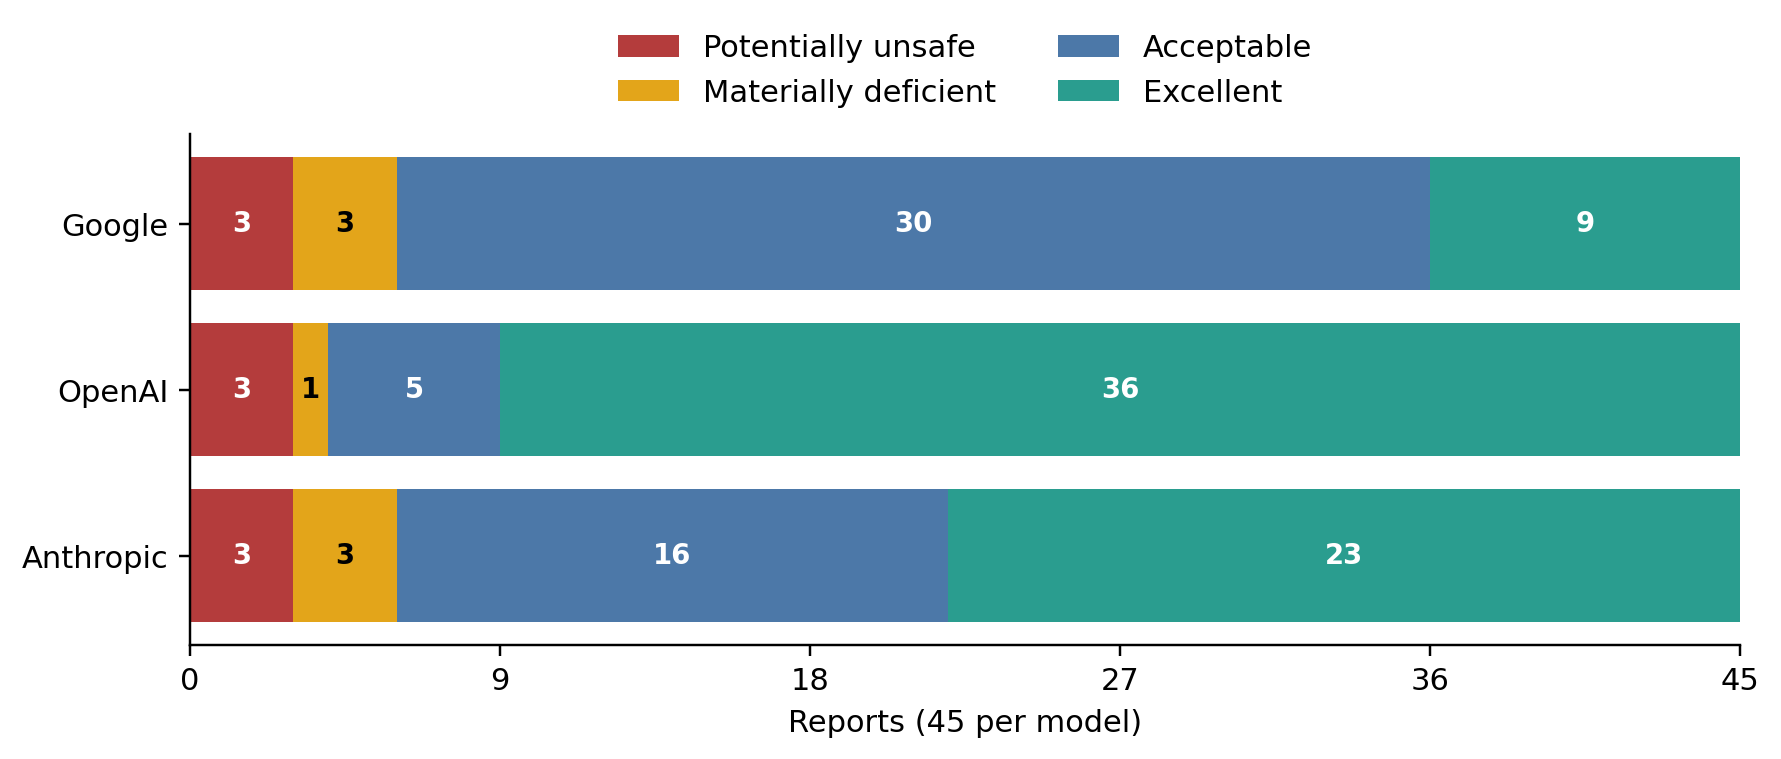
These descriptive results do not, by themselves, establish comparative safety or effectiveness.
#Material clinical failure
Material clinical failure occurred in 6 of 45 Google reports (13.33%), 4 of 45 OpenAI reports (8.89%), and 6 of 45 Anthropic reports (13.33%).
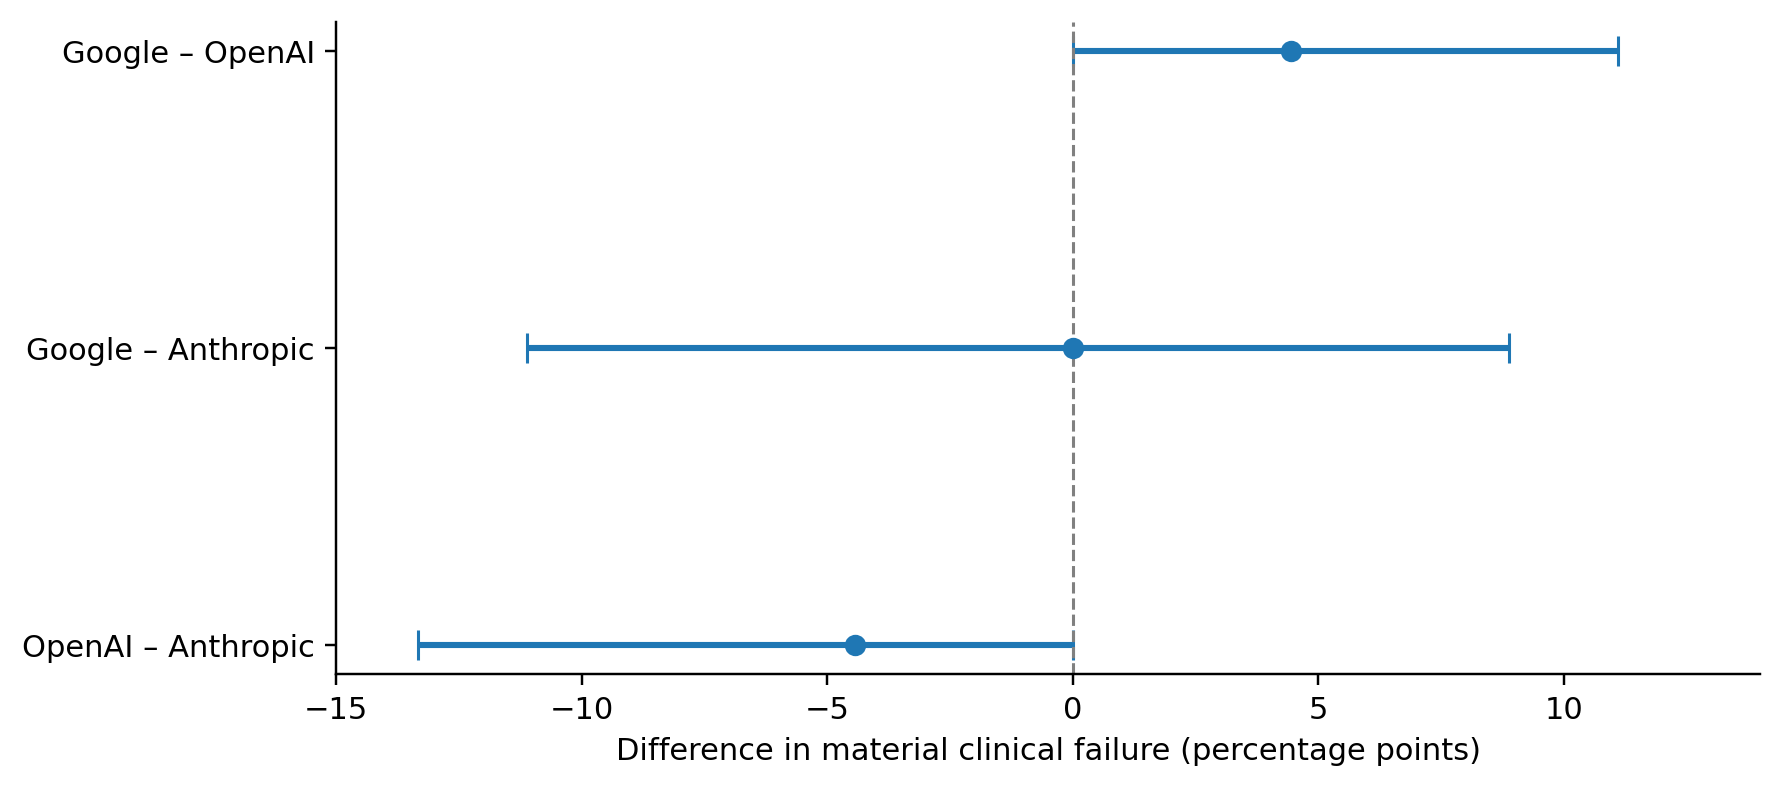
The paired 95% confidence intervals for every between-model difference included zero. The study therefore did not establish superiority, equivalence, or noninferiority among the models for material clinical failure.
#Shared safety signal
All nine reports classified as potentially unsafe occurred in the same complex case, Case 20. All three models received that classification in all three repetitions under the prespecified physician standard.
This shared case-level signal must not be interpreted as a 6.7% real-world unsafe rate. The cohort was small, synthetic, and purposively constructed; it was not a prevalence sample.
#Repeatability
Exact agreement across all three repetitions occurred in 7 of 15 Google cases, 11 of 15 OpenAI cases, and 8 of 15 Anthropic cases.
Repeatability alone does not establish safety. All three models were highly repeatable on Case 20 while repeatedly failing the same safety standard.
#LLM-as-judge finding
The study scheduled 405 judge evaluations. Of these, 322 were valid and 83 failed procedurally. Restricting analysis to reports with valid assessments from all three judges excluded every potentially unsafe report.
This is a methodological observation about automated LLM evaluation in this study. It is not proof that LLM judging is unreliable in all settings.
#Case-level material clinical failure
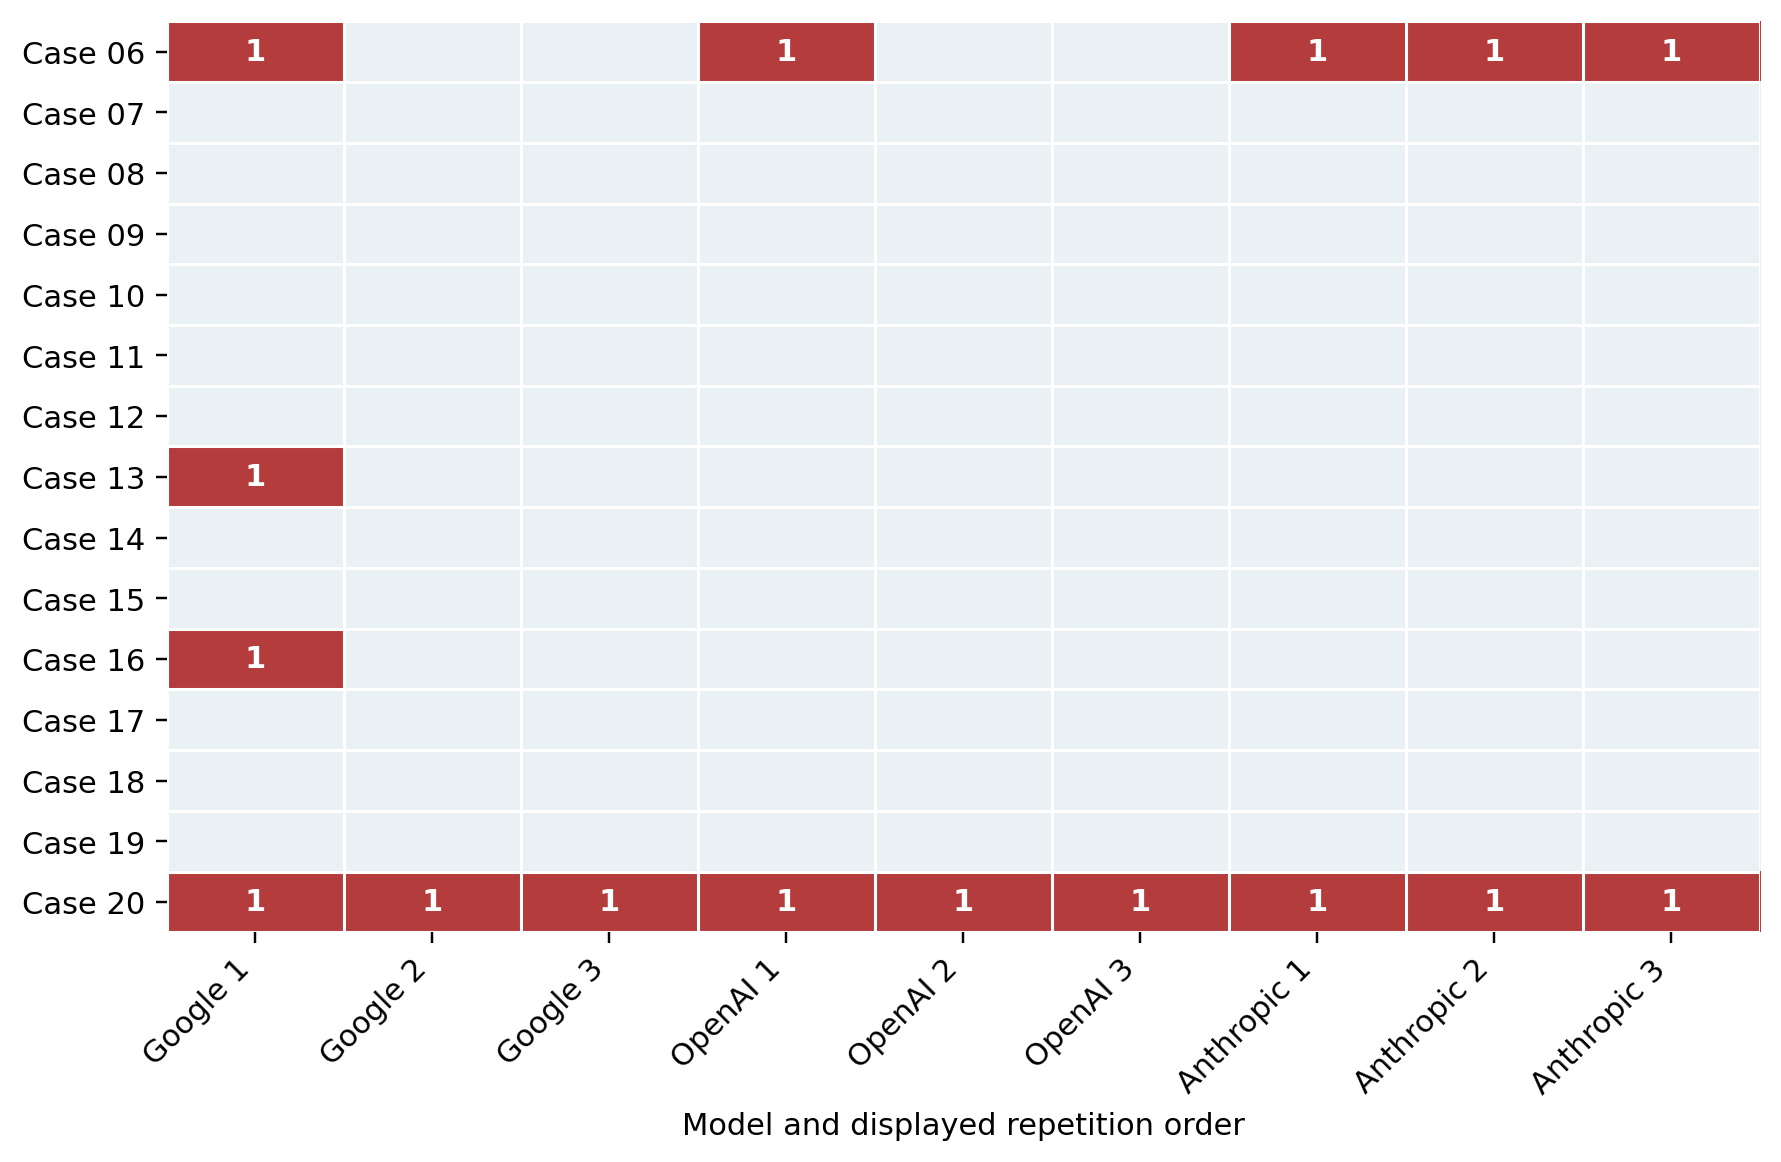
The heatmap shows why aggregate rates and repeatability should be interpreted alongside case-level patterns. The same clinical challenge can recur across models and repetitions.
#Why HealthRadar conducted Yardstick
HealthRadar is investigating how patient-facing interpretation of laboratory results can be evaluated for clinical prioritization, urgency, uncertainty, communication quality, and reproducibility. Yardstick is a research project and should not be presented as a commercial AI-ranking service or as proof of HealthRadar product effectiveness.
#Limitations
- The study used synthetic cases.
- The cohort was a purposive set of 15 cases.
- Each model generated three repetitions per case.
- Findings apply to the specific model versions and API configurations studied.
- Physician adjudication was selective rather than independent physician scoring of every report.
- The study measured no patient outcomes.
- The results do not support inference about real-world error prevalence.
#Collaboration
Interested in studying clinical AI evaluation, laboratory-result communication, or governed AI? We welcome conversations with researchers, clinicians, health systems, and other potential collaborators.